Text-to-Motion
Animation & Motion
Open Source
-
ARDY Discovered by AI
2026
An autoregressive diffusion framework with hybrid representations designed for real-time, interactive 3D human motion generation from text prompts and kinematic constraints.
autoregressiveinteractivemotion-generation -
DrawMotion Discovered by AI
2026
A diffusion-based framework that generates 3D human motions from both conventional text prompts and freehand drawings, offering precise semantic and spatial control.
motion-generationsketch-to-motiontext-to-motion -
FRoM-W1 Discovered by AI
2026
An open-source framework designed to achieve general humanoid whole-body motion control and execution using natural language instructions.
humanoidmotion-generationtext-to-motion -
HandX Discovered by AI
2026
A unified foundation and dataset for scaling bimanual motion and dexterous hand-object interaction generation from text, capturing fine-grained finger dynamics and contact timing.
bimanualdexterous-interactionhand-motion -
Kimodo Discovered by AI
2026
An expressive and controllable kinematic motion diffusion model developed by NVIDIA that scales up human motion generation from text prompts and kinematic constraints.
diffusionmotion-generationtext-to-motion -
KV-Control Discovered by AI
2026
A parameter-efficient trajectory control mechanism for text-to-motion models that injects key/value attention biases to guide characters along specific paths or joint trajectories while preserving the original motion prior.
motion-generationtext-to-motiontrajectory-control -
LaMoGen: Language to Motion Generation Through LLM-Guided Symbolic Inference Discovered by AI
2026
A text-to-motion generation framework that utilizes LLM-guided symbolic inference and a body-part-level symbolic representation called LabanLite. It translates natural language instructions into precise, explainable, and temporally accurate human motions.
explainable-aillmmotion-generationsymbolic-inference -
MoLA-Align: Exploring Motion-Language Alignment for Text-driven Motion Generation Discovered by AI
2026
MoLA-Align explores motion-language alignment for text-driven motion generation, establishing a robust framework to align textual descriptions with 3D human motion sequences. It improves the semantic consistency and physical plausibility of generated animations.
alignmentmotion-generationtext-to-motion -
MoScale: Next-Scale Autoregressive Models for Text-to-Motion Generation Discovered by AI
2026
A next-scale autoregressive framework that generates 3D human motion hierarchically from coarse to fine temporal resolutions. By providing global semantics at the coarsest scale and refining them progressively, it establishes a causal hierarchy better suited for long-range motion structure.
autoregressivehierarchicalmotion-generationtext-to-motion -
MotionHiFlow Discovered by AI
2026
A text-to-motion generation framework that utilizes hierarchical flow matching to model human movements across multiple temporal scales, improving semantic alignment and temporal coherence.
flow-matchingmotion-generationtext-to-motion -
MultiAct Discovered by AI
2026
An unpaired, inference-time framework for text-to-motion generation that uses tailored attention guidance to handle composite prompts describing multiple simultaneous actions.
attention-guidancemotion-generationtext-to-motion -
2025
Animates arbitrary 3D meshes from text prompts, generating 4D mesh motion (per-vertex deformation over time) for fast dynamic-asset creation.
4dmesh-animationtext-driven -
HY-Motion 1.0 Discovered by AI
2025
A billion-parameter text-to-3D human motion generation model based on Diffusion Transformer (DiT) and flow matching, enabling high-quality, instruction-following character animations.
ditflow-matchingmotion-generationtext-to-motion -
InterAct Discovered by AI
2025
A large-scale 3D human-object interaction (HOI) generation framework and benchmark. It addresses the challenges of generating dynamic and physically plausible 3D human-object interactions from textual descriptions, minimizing contact penetration and floating artifacts.
human-object-interactionmotion-generationtext-to-motion -
MoLingo Discovered by AI
2025
A text-to-motion model that generates realistic, lifelike human motion by performing diffusion in a continuous, semantically aligned latent space.
latent-diffusionmotion-generationtext-to-motion -
MoSa: Motion Generation with Scalable Autoregressive Modeling Discovered by AI
2025
A hierarchical motion generation framework that enhances the Vector Quantization-guided Generative Transformers paradigm through a coarse-to-fine scalable generation process.
autoregressivetext-to-motionvq-vae -
Motion Anything: Any to Motion Generation Discovered by AI
2025
An any-to-motion generation framework that enables fine-grained spatial and temporal control over generated motion by introducing an attention-based mask modeling strategy to prioritize dynamic frames and body parts.
mask-modelingmotion-generationtext-to-motion -
MotionGPT3 Discovered by AI
2025
A bimodal motion-language model that processes arbitrary input sequences of motion or language and generates outputs in either modality. It avoids quantization-induced artifacts by encoding raw motion into a continuous latent space using a variational autoencoder (VAE) while leveraging the semantic prior of pretrained language models.
llmmotion-generationmultimodaltext-to-motion -
MotionLab Discovered by AI
2025
A unified human motion generation and editing framework based on the Motion-Condition-Motion (MCM) paradigm. It supports diverse tasks including text-to-motion, motion inbetweening, and fine-grained motion editing within a single model.
motion-editingmotion-generationtext-to-motion -
PersonaBooth Discovered by AI
2025
A personalized text-to-motion generation framework that customizes motion styles and actor personas from a few reference motions using a multi-modal finetuning approach.
motion-generationpersonalizationtext-to-motion -
ReAlign: Text-to-Motion Generation via Step-Aware Reward-Guided Alignment Discovered by AI
2025
ReAlign is a plug-and-play reward-guided sampling alignment framework that uses step-aware reward gradients to guide the reverse sampling trajectory of diffusion models for text-to-motion generation.
diffusion-modelmotion-generationtext-to-motion -
ReMoMask: Retrieval-Augmented Masked Motion Generation Discovered by AI
2025
A retrieval-augmented masked text-to-motion generation framework that unifies retrieval-augmented generation (RAG) with masked diffusion to synthesize temporally coherent and semantically aligned human motions.
masked-diffusionragtext-to-motion -
SnapMoGen Discovered by AI
2025
A text-to-motion generation framework trained on a high-quality dataset featuring expressive and detailed textual annotations for fine-grained control.
datasetmotion-generationtext-to-motion -
TSTMotion: Training-free Scene-aware Text-to-motion Generation Discovered by AI
2025
TSTMotion is a training-free, scene-aware text-to-motion generation framework. It enables the synthesis of realistic human motion sequences interacting with diverse 3D indoor environments without requiring expensive ground-truth scene-motion training data.
3d-scenescene-awaretext-to-motiontraining-free -
AnimationGPT Discovered by AI
2024
An open-source generative AI tool specifically designed for generating game combat motion assets from text prompts. It is trained on MotionGPT and introduces the CombatMotion dataset, which is tailored for game-style combat animations.
combatmotiongame-combatmotion-generationtext-to-motion -
AToM: Aligning Text-to-Motion Model at Event-Level with GPT-4Vision Reward Discovered by AI
2024
A framework that enhances the alignment between generated 3D human motion and event-level text prompts by leveraging feedback and rewards from GPT-4Vision.
alignmentmotion-generationtext-to-motion -
Large Motion Model (LMM) Discovered by AI
2024
A unified, motion-centric multi-modal framework that scales human motion generation across multiple tasks, including text-to-motion and music-to-dance, within a single generalist model.
foundation-modelmotion-generationmulti-modal -
Light-T2M Discovered by AI
2024
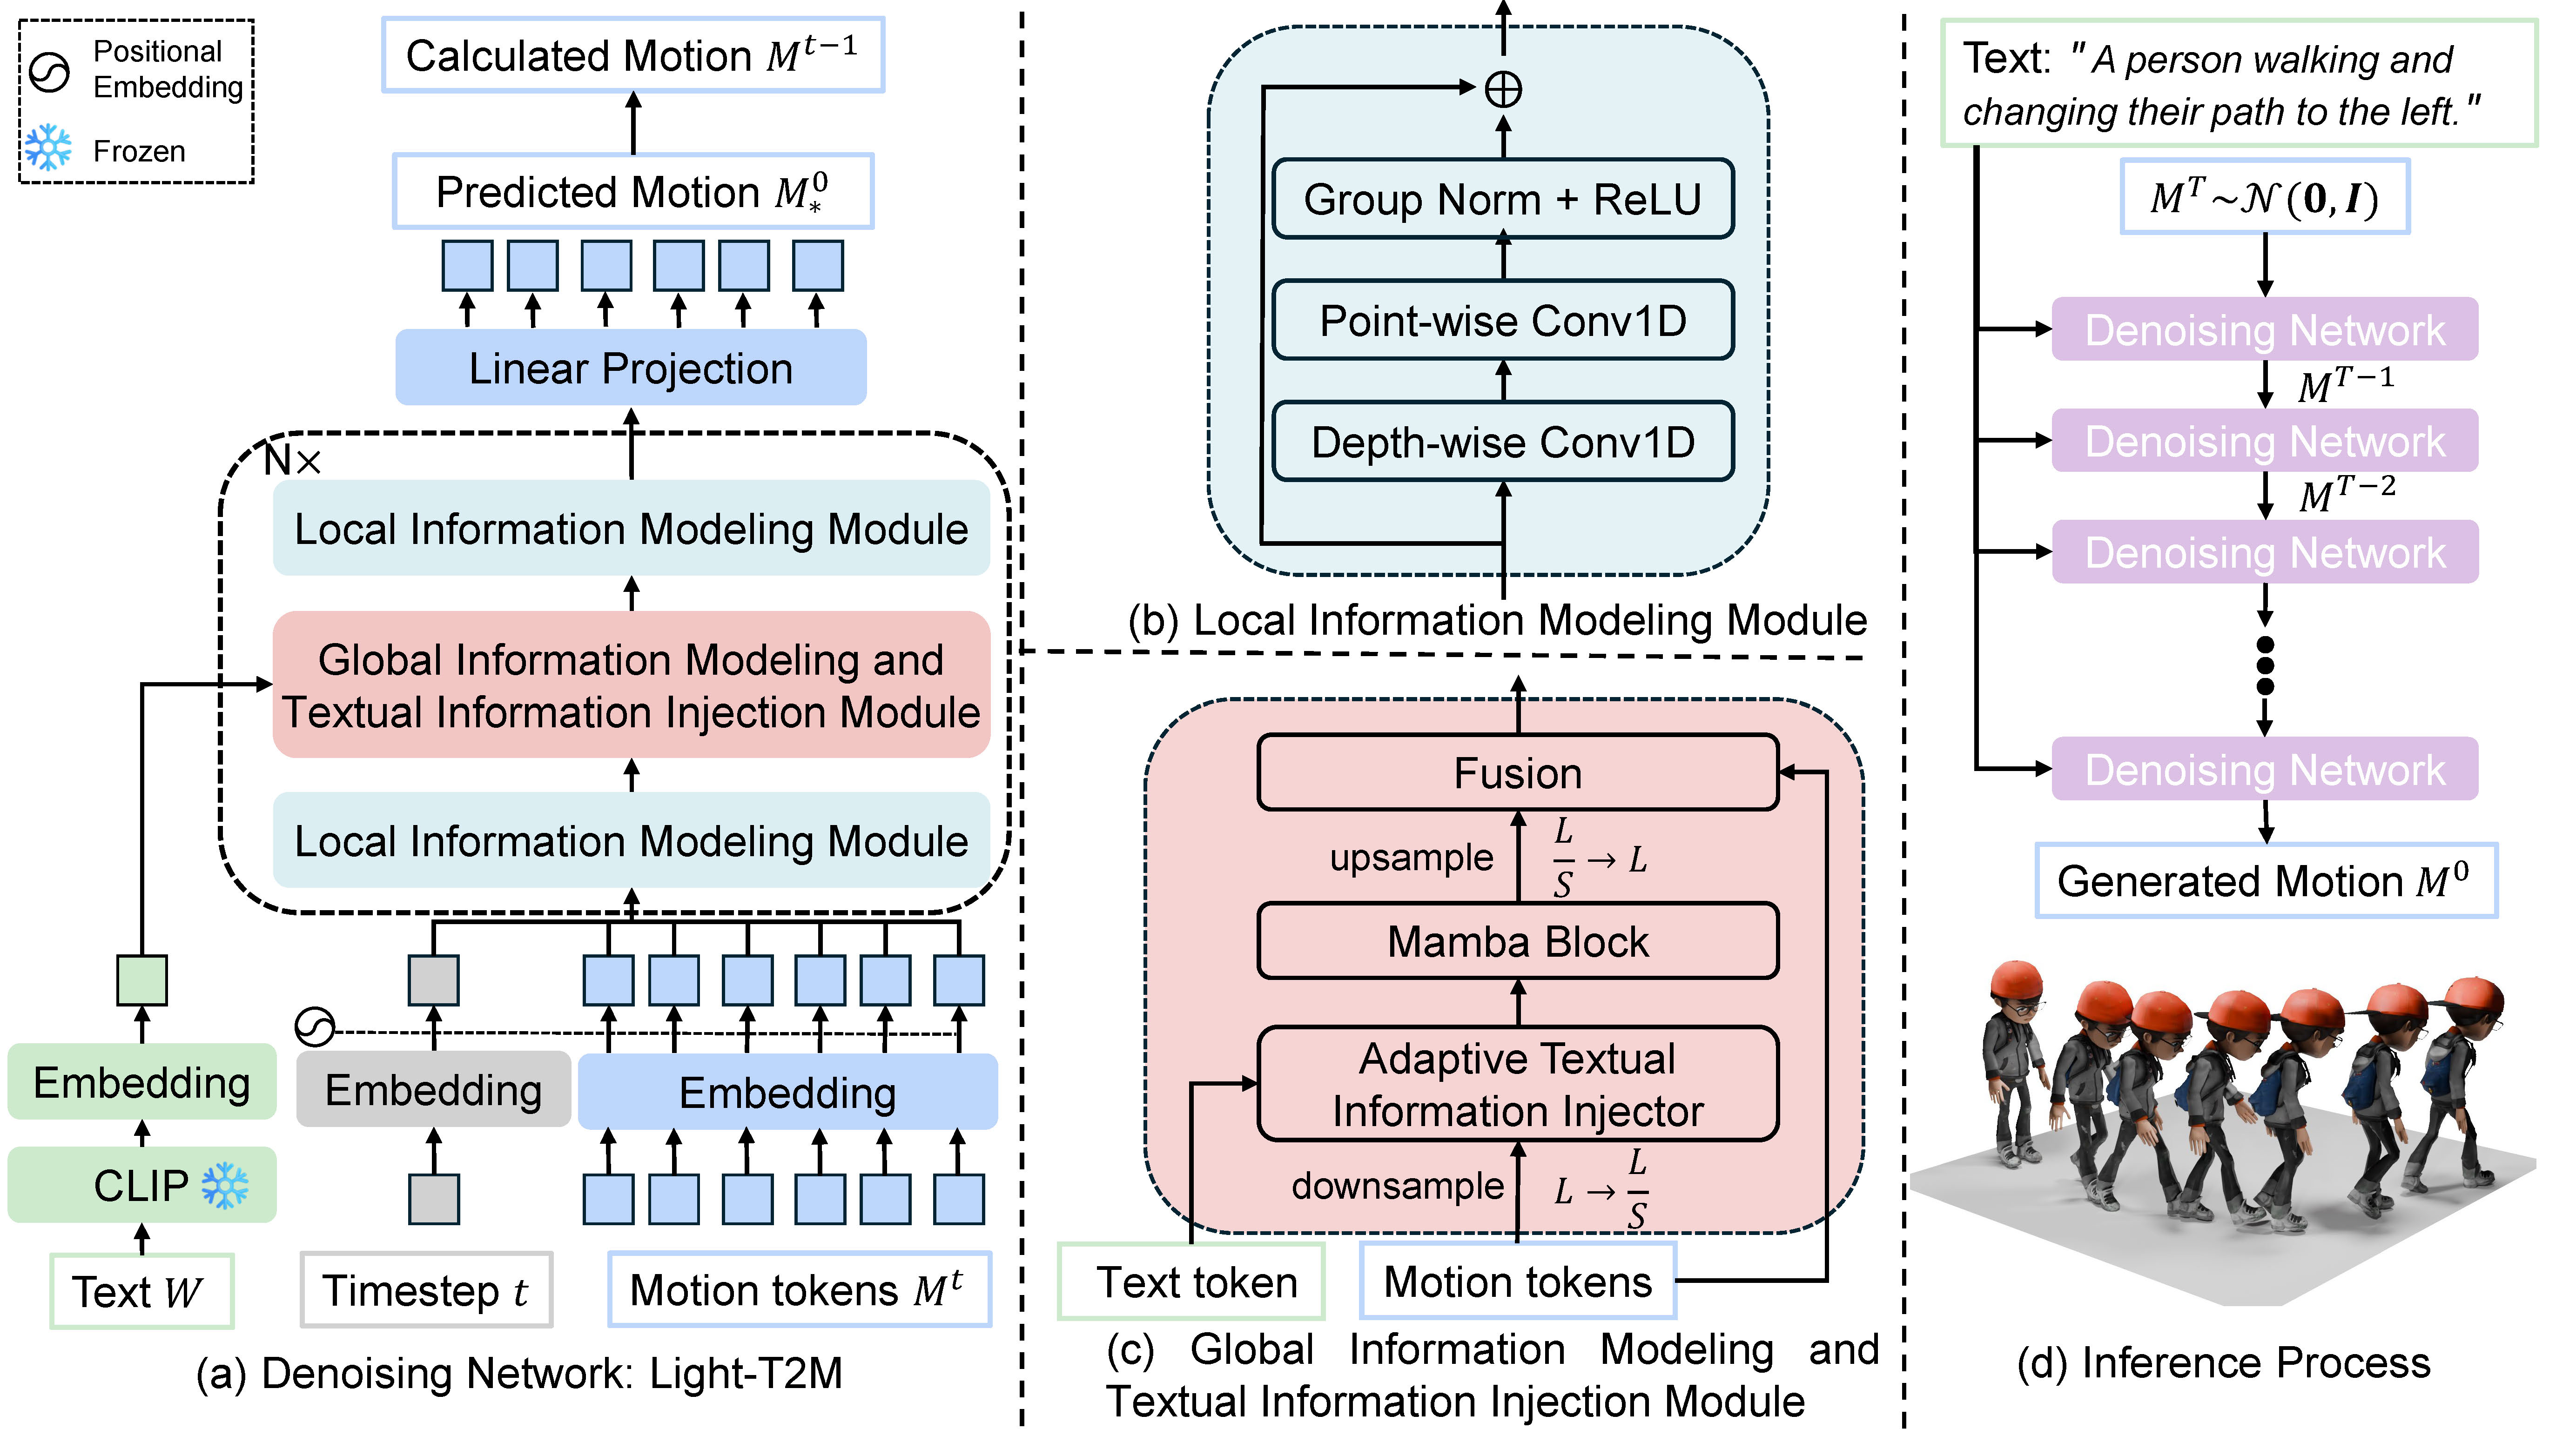
Light-T2M is a lightweight, fast text-to-motion generation framework (AAAI 2025) that combines local motion modeling with an adaptive textual injector to achieve low parameter counts and high inference speed.
3d-animationlightweightreal-timetext-to-motion -
MARDM Discovered by AI
2024
A text-to-motion framework that addresses the limitations of vector quantization (VQ)-based discrete methods by using masked autoregression on continuous motion representations, preserving motion diversity and quality.
diffusionmotion-generationtext-to-motion -
Motion-Agent: A Conversational Framework for Human Motion Generation with LLMs Discovered by AI
2024
An efficient conversational framework for human motion generation, editing, and understanding that utilizes a pre-trained language model to bridge the gap between motion and text.
conversational-agentllmtext-to-motion -
MotionGPT3: Human Motion as a Second Modality Discovered by AI
2024
MotionGPT3 is a unified motion-language framework that models human motion as a second modality, utilizing a Mixture-of-Tokens (MoT) architecture to achieve high-fidelity motion understanding and generation. It enables seamless bidirectional translation between natural language and 3D human motion.
llmmotion-generationtext-to-motion -
MotionLCM: Real-time Controllable Motion Generation via Latent Consistency Model Discovered by AI
2024
Introduces a real-time controllable text-to-motion generation framework based on latent consistency models, enabling high-quality 3D human motion synthesis in just a few denoising steps.
consistency-modelmotion-generationreal-timetext-to-motion -
Multi-Track Timeline Control (STMC) Discovered by AI
2024
Developed by NVIDIA and MPI, this framework enables multi-track timeline control for text-to-motion generation, allowing animators to layer, sequence, and edit text-conditioned motions with accurate timing.
3d-animationnvidiatext-to-motiontimeline-control -
ParCo: Part-Coordinating Text-to-Motion Synthesis Discovered by AI
2024
A part-coordinating text-to-motion synthesis method that introduces part partition and coordination mechanisms to achieve fine-grained, realistic motion generation.
motion-generationpart-coordinationtext-to-motion -
ScaMo Discovered by AI
2024
A scalable autoregressive motion generation framework designed to explore scaling laws in text-to-motion tasks. It features a Motion FSQ-VAE tokenizer for stable, high-fidelity motion quantization and a text-prefix autoregressive transformer, scaling up to 3 billion parameters.
motion-generationscaling-lawtext-to-motion -
SoPo: Text-to-Motion Generation Using Semi-Online Preference Optimization Discovered by AI
2024
SoPo (Semi-Online Preference Optimization) is a reinforcement learning-based fine-tuning framework for text-to-motion models. It combines the advantages of online and offline direct preference optimization (DPO) to consistently generate high-quality, human-preferred 3D motions while avoiding overfitting and biased sampling.
diffusion-modelfine-tuningpreference-optimizationtext-to-motion -
TeSMo: Generating Human Interaction Motions in Scenes with Text Control Discovered by AI
2024
A scene-aware text-to-motion generation framework based on denoising diffusion models that incorporates goal-reaching constraints and scene interaction.
diffusionmotion-generationtext-to-motion -
Text-To-VRMA Discovered by AI
2024
An open-source web application designed to generate VRM Animation (.vrma) files from text descriptions. It supports Japanese and English prompts, utilizes LLM keyframing and NVIDIA ARDY engines, and allows users to preview animations on VRM characters directly in the browser.
text-to-motionvrmvrmavtuber -
VersatileMotion: A Unified Framework for Motion Synthesis and Comprehension Discovered by AI
2024
A unified framework that adapts Large Language Models (LLMs) via a Motion Tokenizer and an autoregressive Transformer to perform both motion generation and motion understanding tasks.
llmmotion-understandingtext-to-motion -
MoMask Discovered by AI
2023
A generative masked modeling framework for text-driven 3D human motion generation. It represents human motion as multi-layer discrete motion tokens using a hierarchical quantization scheme, then generates them using bidirectional transformers.
masked-modelingmotion-generationtext-to-motion -
MotionGPT Discovered by AI
2023
A unified motion-language generation model that treats human motion as a foreign language. It tokenizes 3D motion into discrete codes and trains a large language model on both text and motion tokens to perform text-to-motion, motion-to-text, and motion prediction.
llmmotion-generationtext-to-motion -
MotionGPT: Finetuned LLMs are General-Purpose Motion Generators Discovered by AI
2023
MotionGPT is a unified motion-language framework that treats multimodal control signals, such as text and single-frame poses, as special input tokens in large language models (LLMs) to generate consecutive human motions. It leverages the strong language generation and zero-shot transfer abilities of pre-trained LLMs for diverse motion-related tasks.
llmmotion-generationtext-to-motion -
T2M-GPT Discovered by AI
2023
A simple and effective conditional generative framework based on Vector Quantized-Variational AutoEncoder (VQ-VAE) and Generative Pre-trained Transformer (GPT) for human motion generation from textual descriptions.
gptmotion-generationtext-to-motionvq-vae -
Human Motion Diffusion Model (MDM)
2022
A lightweight diffusion model that generates human motion from text or actions, a common baseline for text-to-motion in animation research.
diffusionmotion-generation -
Motion Latent Diffusion (MLD) Discovered by AI
2022
A fast and high-quality motion diffusion model that operates in a low-dimensional latent space. It establishes a joint latent space between motion and text modalities, enabling efficient and diverse text-to-motion generation.
diffusion-modelmotion-generationtext-to-motion -
MotionDiffuse Discovered by AI
2022
One of the first diffusion model-based text-driven motion generation frameworks, enabling diverse and fine-grained 3D human motion synthesis.
diffusionmotion-generationtext-to-motion

Proprietary / Industry Tools
-
Cartwheel Discovered by AI
2024
A generative AI animation platform designed to create production-ready 3D character animations from text prompts or reference videos.
commercialmotion-generationtext-to-motion -
SayMotion Discovered by AI
2024
A web-based generative AI platform by DeepMotion that transforms text prompts into high-fidelity 3D character animations, supporting exports to FBX, GLB, and BVH formats.
motion-generationonline-toolproprietarytext-to-motion -
SayMotion by DeepMotion Discovered by AI
2024
A commercial browser-based generative AI service that transforms natural language text prompts into high-quality 3D character animations.
commercialmotion-generationtext-to-motion -
Unity Muse Animate Discovered by AI
2024
Unity's official AI-powered animation tool that allows developers to generate and edit natural-looking character animations directly inside the Unity Editor using text prompts and ML-assisted posing.
commercialmotion-generationtext-to-motionunity