Text-to-Speech
Audio
Open Source
-
Fish Audio S2 Discovered by AI
2026
An advanced open-source text-to-speech system featuring multi-speaker, multi-turn generation, and instruction-following control via natural-language descriptions. It utilizes a staged data pipeline and reward modeling to achieve state-of-the-art multilingual voice generation and cloning.
instruction-followingmultilingualttsvoice-cloning -
Supertonic Discovered by AI
2026
A lightning-fast, on-device multilingual text-to-speech system designed for local inference with minimal overhead. Powered by ONNX Runtime, it supports 31 languages and is highly optimized for real-time applications like games.
multilingualon-deviceonnxtts -
VoxCPM2 Discovered by AI
2026
A fully open-source multilingual and controllable speech generation foundation model based on a hierarchical diffusion-autoregressive paradigm. It supports 30 languages, natural-language voice design, style-controllable voice cloning, and high-fidelity 48kHz audio output.
diffusionmultilingualttsvoice-cloning -
IndexTTS Discovered by AI
2025
IndexTTS is an industrial-level controllable zero-shot text-to-speech system that incorporates character and phoneme hybrid modeling for enhanced pronunciation accuracy.
controllableindustrial-ttsttszero-shot -
IndexTTS2 Discovered by AI
2025
An industrial-level, emotionally expressive, and duration-controlled autoregressive zero-shot text-to-speech system. It introduces a novel method for precise speech duration control and faithful emotion replication, making it highly suitable for interactive dialogue applications.
duration-controlemotion-controlttszero-shot -
Zonos Discovered by AI
2025
An open-weight text-to-speech model trained on over 200,000 hours of multilingual speech, offering high expressiveness, voice cloning, and precise control over speaking rate, pitch, and emotion.
speech-synthesisttsvoice-cloning -
ChatTTS Discovered by AI
2024
A generative speech model optimized for daily conversational scenarios, supporting multiple speakers, interactive dialogue, and natural non-verbal elements like laughter and pauses.
conversationaldialoguetts -
CosyVoice Discovered by AI
2024
A multi-lingual large voice generation model developed by Alibaba's FunAudioLLM, supporting high-quality speech synthesis, zero-shot voice cloning, and fine-grained control over emotion and style.
multilingualttsvoice-cloning -
CosyVoice Discovered by AI
2024
A highly scalable multilingual zero-shot text-to-speech synthesizer developed by Alibaba's FunAudioLLM. It utilizes a large language model for text-to-token generation and a conditional flow matching model for token-to-speech synthesis, enabling high-quality voice cloning, cross-lingual synthesis, and emotional control.
flow-matchingmultilingualttsvoice-cloning -
E2 TTS Discovered by AI
2024
A fully non-autoregressive zero-shot text-to-speech system that offers human-level naturalness and state-of-the-art speaker similarity and intelligibility. It uses a flow-matching-based mel spectrogram generator trained on character sequences with filler tokens, bypassing the need for complex alignment or duration modeling.
flow-matchingnon-autoregressivettszero-shot -
F5-TTS Discovered by AI
2024
A non-autoregressive text-to-speech system based on Flow Matching and Diffusion Transformer (DiT) with ConvNeXt V2, offering highly natural, expressive, and fast zero-shot voice cloning.
diffusionttsvoice-cloning -
FireRedTTS Discovered by AI
2024
A foundation text-to-speech framework designed for industry-level generative speech applications. It features a robust data processing pipeline, a text-to-speech language model mapping text to semantic tokens, and a flow-matching-based mel-spectrogram decoder for highly natural and personalized speech synthesis.
flow-matchingfoundation-modelspeech-synthesistts -
Fish Speech Discovered by AI
2024
A state-of-the-art multilingual text-to-speech system that leverages large language models and a Dual-Autoregressive architecture to achieve highly natural, emotionally rich voice generation and zero-shot cloning.
multilingualttsvoice-cloning -
Fish Speech Discovered by AI
2024
A state-of-the-art open-source text-to-speech system based on a dual-stage architecture (VQ-GAN and LLM) that supports zero-shot voice cloning and highly expressive multilingual speech synthesis.
speech-synthesisttsvoice-cloning -
GPT-SoVITS Discovered by AI
2024
A powerful few-shot voice conversion and text-to-speech system that can clone a voice with as little as 1 minute of training data, supporting zero-shot inference and cross-lingual synthesis.
few-shotttsvoice-cloning -
Kokoro Discovered by AI
2024
A highly efficient, lightweight open-weight text-to-speech model with 82 million parameters that delivers studio-quality, natural-sounding speech across multiple languages.
lightweightmultilingualtts -
Parler-TTS Discovered by AI
2024
An open-source text-to-speech model and training library by Hugging Face that generates high-quality, natural-sounding speech controllable via natural language prompts specifying attributes like gender, background noise, speaking rate, and pitch.
speech-synthesisttsvoice-generationGitHub · arXiv · Hugging Face
-
Parler-TTS Discovered by AI
2024
A lightweight, fully open-source text-to-speech model and training framework that generates high-quality, natural-sounding speech controlled by natural language prompts.
open-sourcespeech-synthesistts -
Style-Bert-VITS2 Discovered by AI
2024
An enhanced version of Bert-VITS2 that introduces highly controllable voice styles and emotions, widely adopted in the anime and game development communities for character voice generation.
anime-voicestyle-controlttsvits2 -
EmotiVoice Discovered by AI
2023
A multi-voice and prompt-controlled text-to-speech engine by NetEase Youdao, supporting highly expressive speech synthesis with fine-grained control over emotions and styles.
emotional-speechneteaseprompt-controltts -
Matcha-TTS Discovered by AI
2023
A fast, lightweight, and high-quality non-autoregressive text-to-speech architecture based on conditional flow matching (CFM) that achieves rapid synthesis with fewer steps.
fast-inferenceflow-matchingtts -
MeloTTS Discovered by AI
2023
A high-quality, lightweight, and extremely fast multilingual text-to-speech library developed by MyShell, supporting English, Spanish, French, Chinese, Japanese, and Korean.
lightweightmultilingualtts -
StyleTTS 2 Discovered by AI
2023
An advanced text-to-speech model that achieves human-level speech synthesis through style diffusion and adversarial training with large speech language models.
style-diffusionttsvoice-cloning -
StyleTTS 2 Discovered by AI
2023
A text-to-speech model that achieves human-level naturalness by utilizing style diffusion and adversarial training with large speech language models.
diffusionspeech-synthesistts -
TorToiSe TTS Discovered by AI
2023
An expressive, multi-voice text-to-speech system trained on a large dataset with an emphasis on quality and realistic prosody. It leverages autoregressive transformers and diffusion models to generate highly natural speech.
diffusiontransformerttsvoice-cloning -
VALL-E X Discovered by AI
2023
An open-source implementation of Microsoft's cross-lingual neural codec language model for zero-shot cross-lingual text-to-speech synthesis and voice cloning. It can synthesize speech in a target language using a short audio prompt from a different source language while preserving the speaker's voice.
codeccross-lingualttsvoice-cloning -
2021
An end-to-end text-to-speech model combining variational inference and adversarial training, the basis for many open Japanese and character TTS voices.
end-to-endtts -
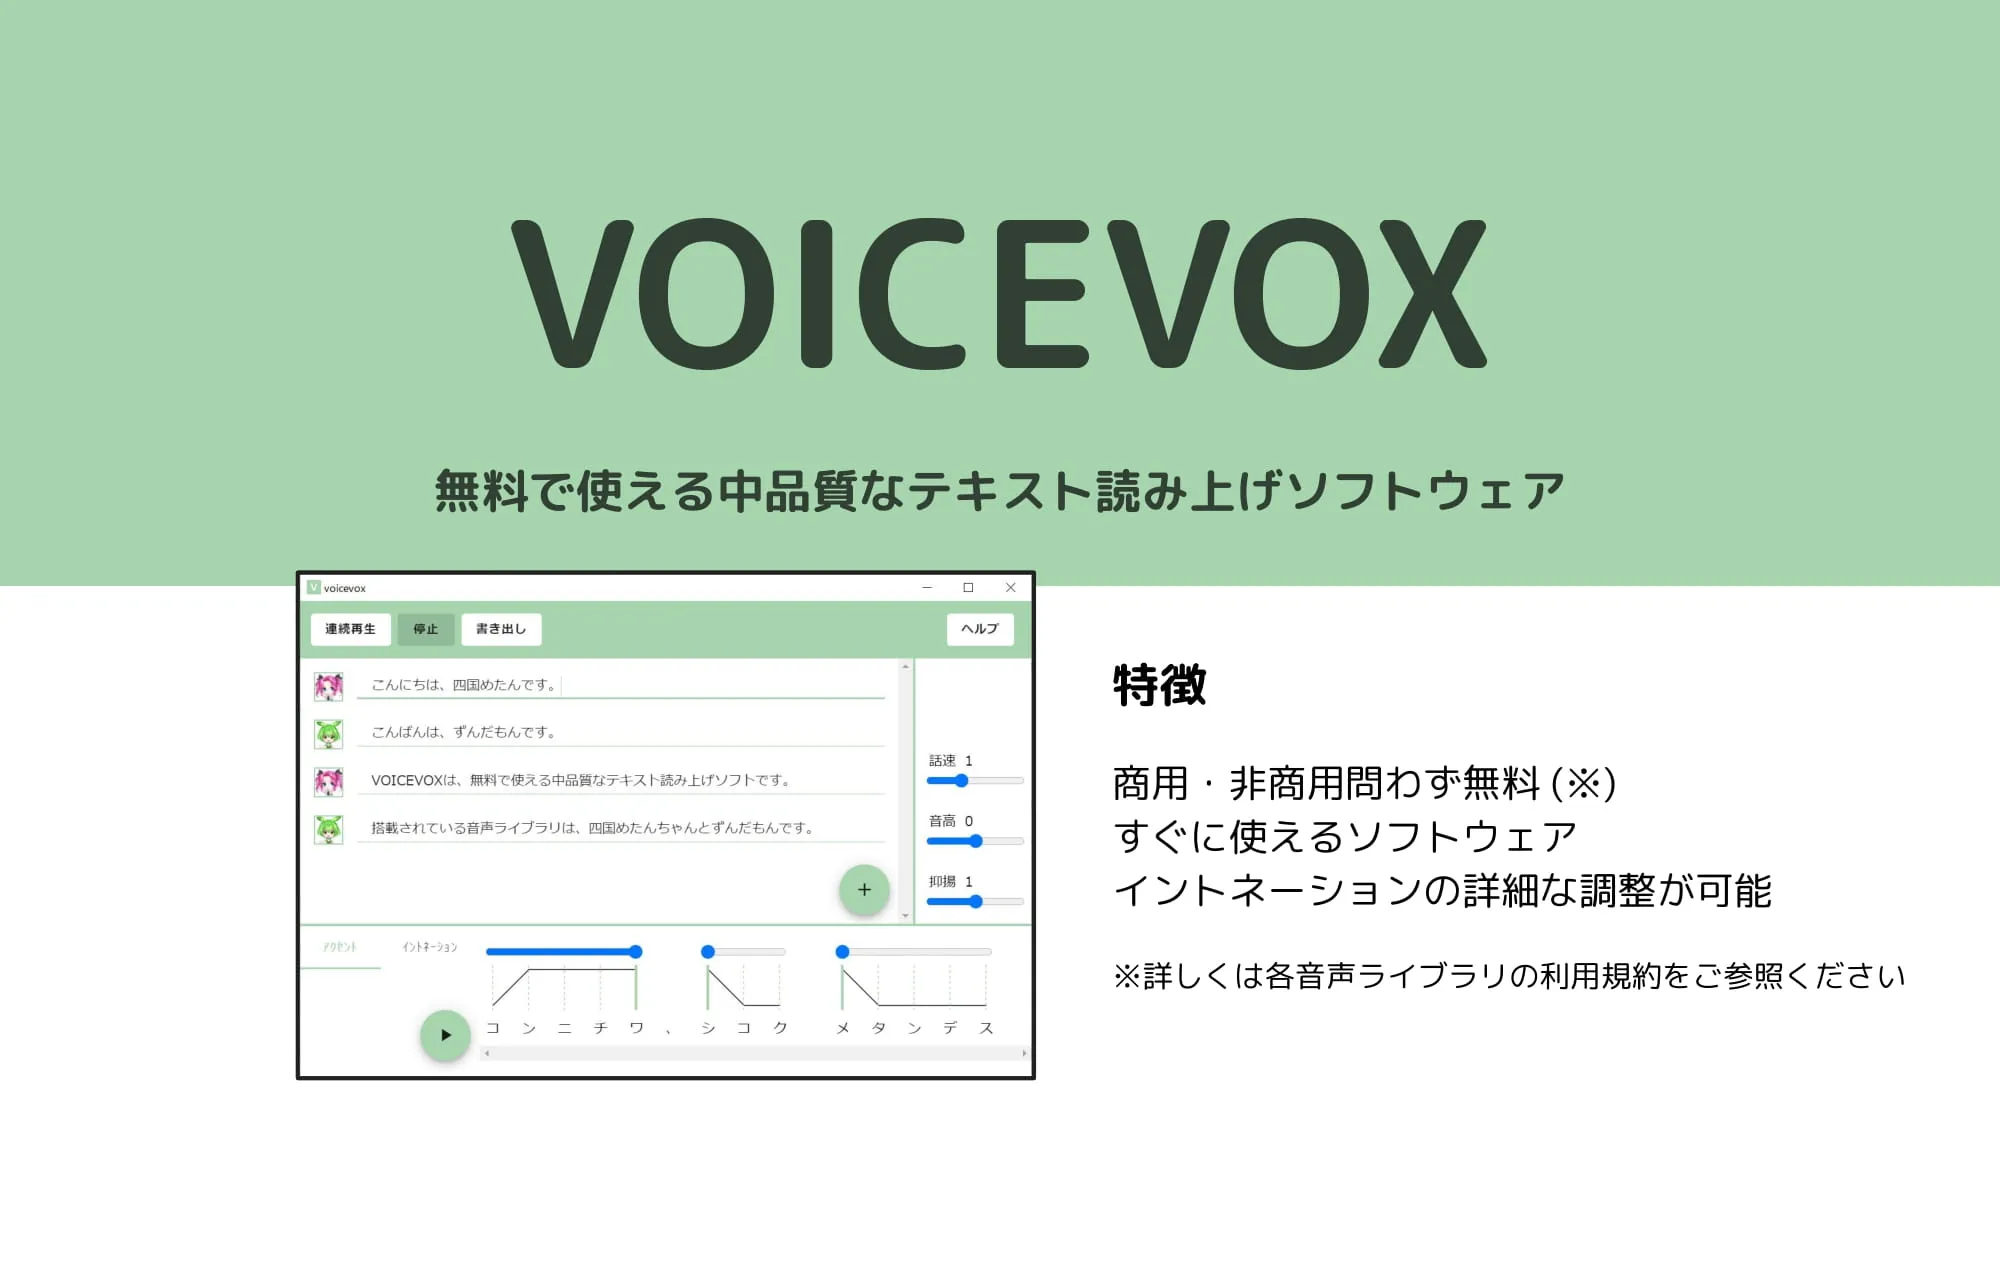
VOICEVOX Discovered by AI
2021
VOICEVOX is an open-source Japanese text-to-speech editor and engine widely used in game development, VTuber content creation, and anime production.
japanesespeech-synthesisttsvoicevox

Proprietary / Industry Tools
-
Cartesia Discovered by AI
2024
A state-of-the-art real-time text-to-speech platform powered by the Sonic model, delivering ultra-low latency (under 100ms) and highly expressive, lifelike voices for interactive applications and AI agents.
low-latencyreal-timetts -
Resemble AI Discovered by AI
2019
An enterprise-grade generative voice platform offering high-fidelity text-to-speech, real-time voice cloning, and deepfake detection with built-in watermarking.
enterprisettsvoice-cloning -
Respeecher Discovered by AI
2018
An enterprise-grade voice cloning and speech synthesis platform widely used in Hollywood films and AAA game production to replicate and transform voices with high emotional fidelity.
game-productionspeech-synthesisvoice-cloningvoice-conversion -
A commercial speech platform offering expressive TTS, voice cloning, dubbing, and sound effects, broadly adopted for game and animation voice-over.
apicommercialdubbingvoice-cloning